Sequential decomposition and attribution for trajectory forecasting

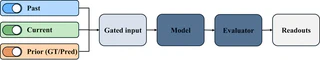 The SDA protocol: inputs are split into Past, Current, and Prior streams, combined through controlled gating, then fed to the forecasting model and evaluator to attribute each stream’s contribution.
Trajectory forecasting models keep getting longer input windows on the assumption that more history means better predictions. In practice that assumption often breaks down: accuracy gains taper off quickly, extra history adds compute cost, and longer windows pull in more noise. SDA is not another forecasting model — it is an evaluation protocol for measuring why a model performs the way it does.
SDA splits any trajectory forecasting input into three interpretable streams and gates them on/off in controlled combinations to measure each one’s standalone value, its marginal contribution on top of the others, and how the streams interact:
- Past — the historical trajectory before the current step
- Current — the most recent observed state
- Prior — an optional destination or goal, when available
Running this protocol on two real-world datasets (Porto taxi, ETH pedestrian) with both an LSTM and a Transformer backbone gives a consistent picture:
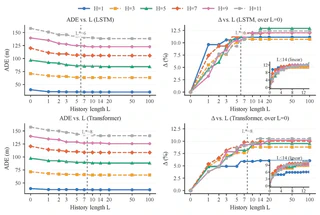
- Accuracy gains from history saturate after a short window (L*≈6–8 steps) regardless of backbone or prediction horizon.
- The Current state alone is already highly informative at short horizons.
- A reliable Prior (goal/destination) gives a bigger boost than piling on more history, especially at longer horizons.
- Past, Current, and Prior show conditional complementarity — their combined value is not simply additive.
The takeaway for model design: prioritize making good use of the latest state and any available goal information, rather than defaulting to ever-longer observation windows.
